Everyone talks about H100s for diffusion model training like they're all created equal, but hourly rates swing from affordable to absurd depending on the provider, and not every platform gives you enough VRAM or persistent storage to finish a full SDXL training cycle. You need a GPU for diffusion models that won't crash, won't cost triple what you budgeted, and won't take half a day to configure. We ranked five cloud providers on the factors that actually matter for generative model training and AI image generation workloads.
TLDR:
Diffusion models are the tech behind AI image generators like Stable Diffusion and SDXL. During training, the model learns to reverse a noise process, iteratively denoising random static into coherent images across thousands of steps. Each step runs dense matrix operations across millions of samples, making GPU memory bandwidth a critical bottleneck.
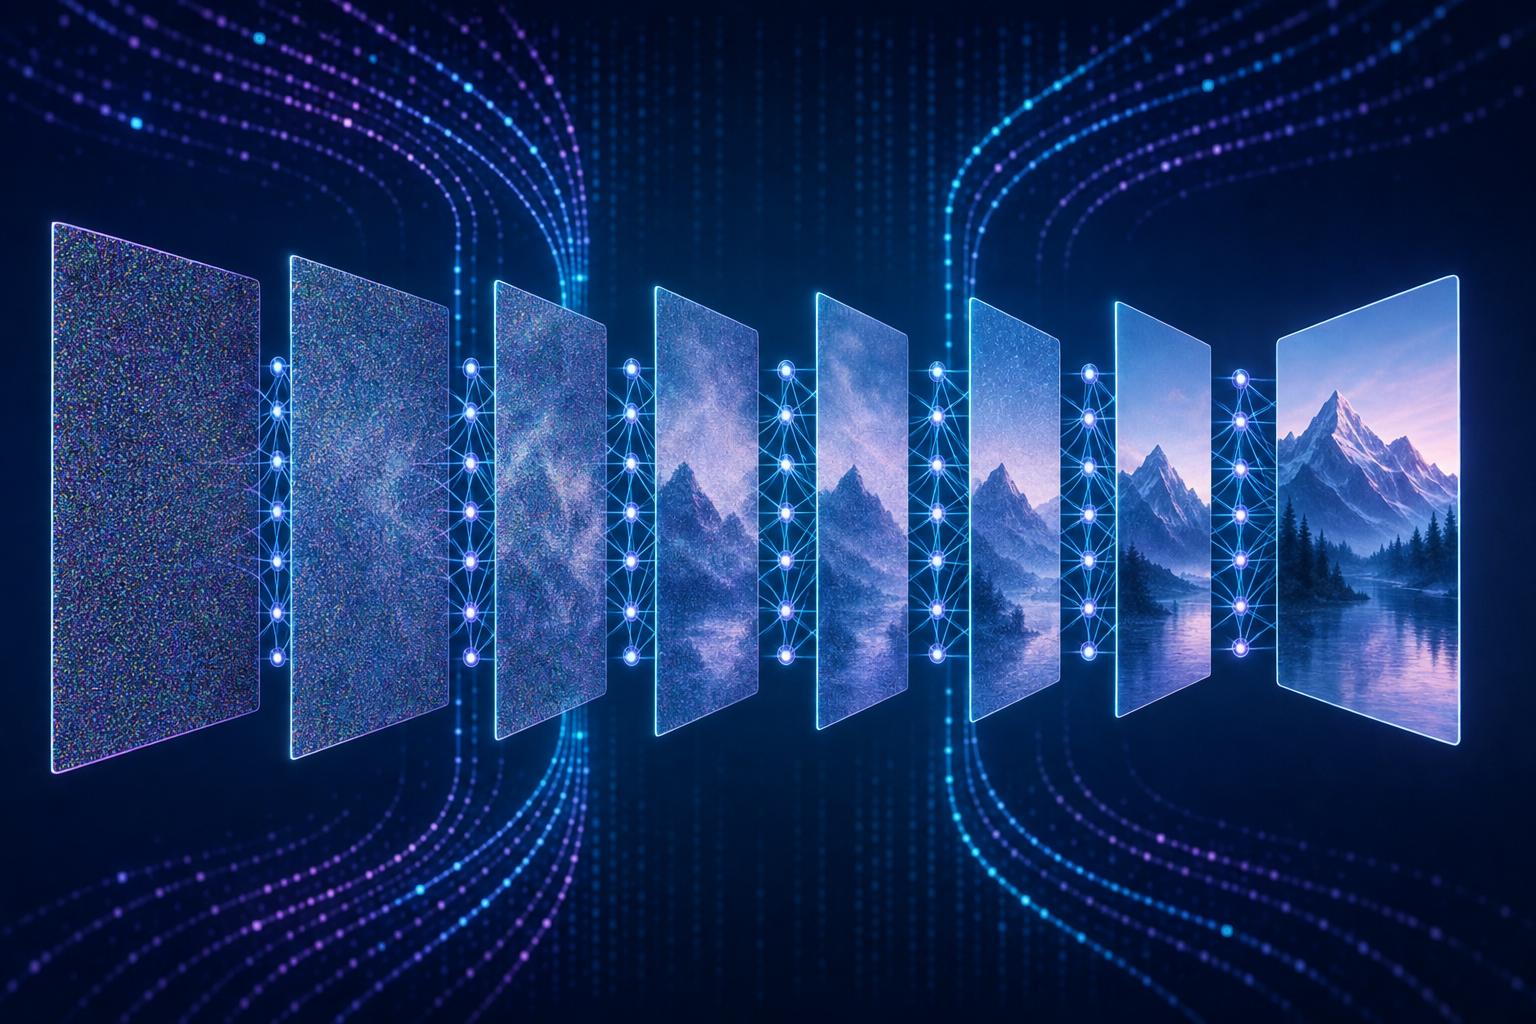
Training even a fine-tuned SDXL variant can take hours of continuous GPU compute. Full runs from scratch stretch into days. VRAM capacity, memory bandwidth, and interconnect speed directly affect how fast a run completes and whether a job fits in memory at all. The wrong GPU means slower iteration, higher costs, and training jobs that crash before finishing. SDXL LoRA training typically requires 10+ GB depending on batch size and precision settings.
Every provider in this list was assessed against the same criteria, drawn from publicly available pricing pages and documentation. No original benchmarking was run.
There are five factors that shaped each ranking.
We built Thunder Compute around a simple premise: GPU compute for AI training shouldn't require enterprise contracts or AWS-level pricing. H100s start at $2.29/hr and scale up to $11.98/hr depending on configuration, running roughly 80% lower than what AWS charges for equivalent hardware.
What we offer for diffusion model training:
A strong fit for teams running SDXL fine-tunes or full diffusion training jobs who want the lowest H100 rates available. Mac users also get out-of-the-box support that no other provider on this list offers.
RunPod is a popular choice for researchers who want flexible, on-demand GPU access without long-term commitments. It offers a wide selection of hardware across community and secure cloud tiers, making it accessible for diffusion model training at various budget levels.
Pricing for H100 instances starts around $2.29/hr, with availability varying by region and demand. The community cloud tier can offer lower rates, though with less uptime consistency than dedicated options.
RunPod supports popular frameworks like Diffusers and Kohya out of the box, and its persistent storage options make iterative SDXL training workflows more practical.
CoreWeave, Lambda Labs, Vast.ai, RunPod, and AWS — all strong names in cloud GPU rentals — but Node.ai carves out a specific niche with its research-first approach. It offers dedicated access to NVIDIA H100 and A100 clusters, which makes it appealing for teams running long diffusion model training jobs that can't afford interruptions from spot preemption.
Node.ai pricing sits in the mid-to-high range for managed GPU services. H100 SXM5 instances run roughly $2.80–$3.50/hr per GPU depending on cluster size and commitment level. For SDXL or full UNet fine-tuning workloads, reserved access means you get consistent throughput without fighting for spot availability.
The tradeoff is flexibility. Node.ai suits labs and research teams with steady, predictable GPU demand better than it suits individual developers spinning up occasional training runs.
Lambda Labs offers on-demand and reserved H100, A100, and A10 instances aimed at AI researchers and teams that want straightforward GPU access without cloud vendor complexity.
Lambda's pricing tends to run below hyperscaler rates, making it a reasonable choice for teams running extended SDXL or diffusion fine-tuning jobs. Reserved instances drop costs further for high-utilization workflows.
Crusoe is a cloud provider built around sustainable computing, powering its GPU clusters with stranded or flared natural gas instead of grid electricity. For diffusion model training, they offer H100 SXM5 nodes with strong interconnect speeds, making them a reasonable choice for teams that care about their carbon footprint without sacrificing raw throughput.
Pricing sits in a competitive range for H100 access, though Crusoe's catalog is narrower than hyperscalers like AWS or Azure. Availability can be inconsistent during high-demand periods, which may slow down teams running iterative SDXL training jobs that require frequent on-demand provisioning.
Atlas Cloud is a GPU cloud provider focused on enterprise AI workloads, offering H100 and A100 clusters with high-speed InfiniBand networking suited for distributed diffusion model training. Their infrastructure targets teams running large-scale generative model training jobs that require low-latency GPU interconnects.
Pricing is competitive for enterprise contracts, though on-demand rates are less transparent than other providers. Teams that need dedicated clusters for long training runs may find Atlas Cloud worth considering, but researchers running shorter experiments may prefer providers with clearer per-hour pricing and faster provisioning times.
Here is a side-by-side breakdown of how each provider compares on the criteria that matter most for diffusion model training.
Thunder Compute Local offers on-demand H100 and A100 GPU access with per-minute billing, so you never pay for idle time between training runs. Setup takes under two minutes, and you get full root access to configure your diffusion model training environment exactly as needed.
Pricing starts at $2.29/hr for H100 access, making it one of the more competitive rates available for serious generative model training workloads. There are no long-term commitments or reserved instance requirements.
For SDXL training and other AI image generation workloads, the combination of fast provisioning, flexible billing, and high-memory GPU options makes Thunder Compute Local a practical choice for researchers and teams scaling up diffusion model experiments.
Running SDXL fine-tuning or full diffusion training jobs means you need GPUs that can handle the memory load without crashing mid-run. Pricing matters, but so does how fast you can get an instance live and whether your checkpoints survive between sessions. We kept Thunder Compute simple: H100s at $2.29/hr, persistent storage for your training state, and VS Code ready to go. Your next generative model training run should start in minutes, not hours.
Start by checking if the provider lists H100 pricing upfront and offers persistent storage for checkpoints. Match your budget to the hourly rate, then verify they support your training framework and offer quick provisioning times to avoid setup delays.
Beginners should look for providers with one-click setup and clear documentation, like Thunder Compute Local's VS Code integration. Advanced users running multi-node distributed training need high-speed interconnects and spot pricing options to optimize costs across longer jobs.
Thunder Compute Local is the only verified provider supporting Apple Silicon for GPU workloads. This lets Mac users access cloud GPU resources natively without compatibility workarounds, though you'll still connect to remote H100s instead of training locally on your device.
Switch to dedicated instances when your training runs exceed 6-8 hours and interruptions would erase progress. Spot pricing saves money on fault-tolerant jobs, but long SDXL fine-tuning runs need guaranteed uptime to avoid restarting from the last checkpoint.
SDXL fine-tuning typically requires at least 24GB VRAM for smaller batch sizes, but 80GB H100 configurations give you headroom for larger batches and faster convergence. Running out of memory mid-training crashes the job, so overestimate your needs by 20-30% when selecting an instance.


